
What Is Incident Management: Your 2026 Guide to Resilience
- Jul 19
- 12 min read
Your phone buzzes at 2 AM. Alerts are firing, the checkout flow is timing out, Slack is filling with guesses, and two engineers are already pushing changes before anyone has confirmed the blast radius. If that feels familiar, you don't have an incident management problem in theory. You have one in production.
What is incident management? It's the discipline teams use to identify, log, and resolve disruptions that affect normal operations. In practice, it's the difference between a controlled response and a public mess. The strongest teams don't treat it like a help desk workflow. They treat it like an operating system for reliability, trust, and recovery under pressure.
Modern incident management also isn't just about reacting faster. It's about preventing avoidable failures, designing clean handoffs, and making sure the right people can execute when systems break.
Table of Contents
Beyond Chaos What Incident Management Really Means - Incident management is organized response under pressure - Reactive teams stay busy proactive teams stay credible
The Five Stages of the Incident Lifecycle - Plan and prepare - Detect and report - Assess and decide - Respond and recover - Learn lessons
Assembling Your Incident Response Team Key Roles - The incident commander keeps people from working at cross purposes - The rest of the team should be small and explicit
Measuring Success KPIs SLAs and SLOs - Start with priority then measure the system - SLOs guide engineering SLAs define the promise
Your Toolkit Essential Tools and Runbook Examples - The stack you actually need - A runbook example for database saturation
Hiring for Resilience The Underrated Skill of Incident Response - Hybrid teams fail at the handoff not just the fix - Hire for judgment under pressure
Build Your Resilient Future with Elite Engineers - Resilience is a systems problem and a talent problem
Beyond Chaos What Incident Management Really Means
A real incident rarely starts with clarity. It starts with noise. A latency spike looks like a network issue, then support reports failed logins, then someone notices background jobs are backing up, and now product wants customer comms before engineering has a reliable timeline.
That's why incident management matters. It gives the team a repeatable way to move from confusion to diagnosis, containment, and recovery without turning the response itself into a second failure.
Incident management is organized response under pressure
Incident management is the IT process used to identify, log, and resolve disruptions that impact normal operations, and that plain definition still matters because it forces discipline when people are tempted to improvise. The best teams log the incident early, assign ownership immediately, establish a single decision-maker, and protect service restoration from side arguments.
If you lead engineering, you also need to think beyond uptime. The technical incident becomes a communication incident fast. Brand damage doesn't wait for your root cause analysis, which is why this guide on brand protection is worth keeping close to your incident playbooks.
Practical rule: If nobody can answer who is in charge, what changed, and what customer impact is confirmed, you're still in chaos.
A mature response also depends on how your team thinks about systems, not isolated alerts. That's where systems thinking in engineering organizations becomes useful. Incidents don't emerge from one broken component alone. They emerge from dependencies, assumptions, and brittle handoffs.
Reactive teams stay busy proactive teams stay credible
The industry has moved hard toward prevention. Proactive responders increased to 68% in 2024, up 12% from the previous year, according to the 2024 State of Incident Management whitepaper. That shift matters because reactive teams spend their time clearing alarms, while proactive teams spend theirs removing repeat failure modes.
You can see the same trend in tooling. More teams are using automation and AI to reduce triage friction and speed up recovery, but tooling only helps when the operating model is sound. If alerts are noisy, ownership is fuzzy, or contractors don't know the service boundaries, AI just helps you fail faster.
So don't define incident management as ticket routing. Define it as the discipline that preserves service reliability when reality stops matching the architecture diagram.
The Five Stages of the Incident Lifecycle
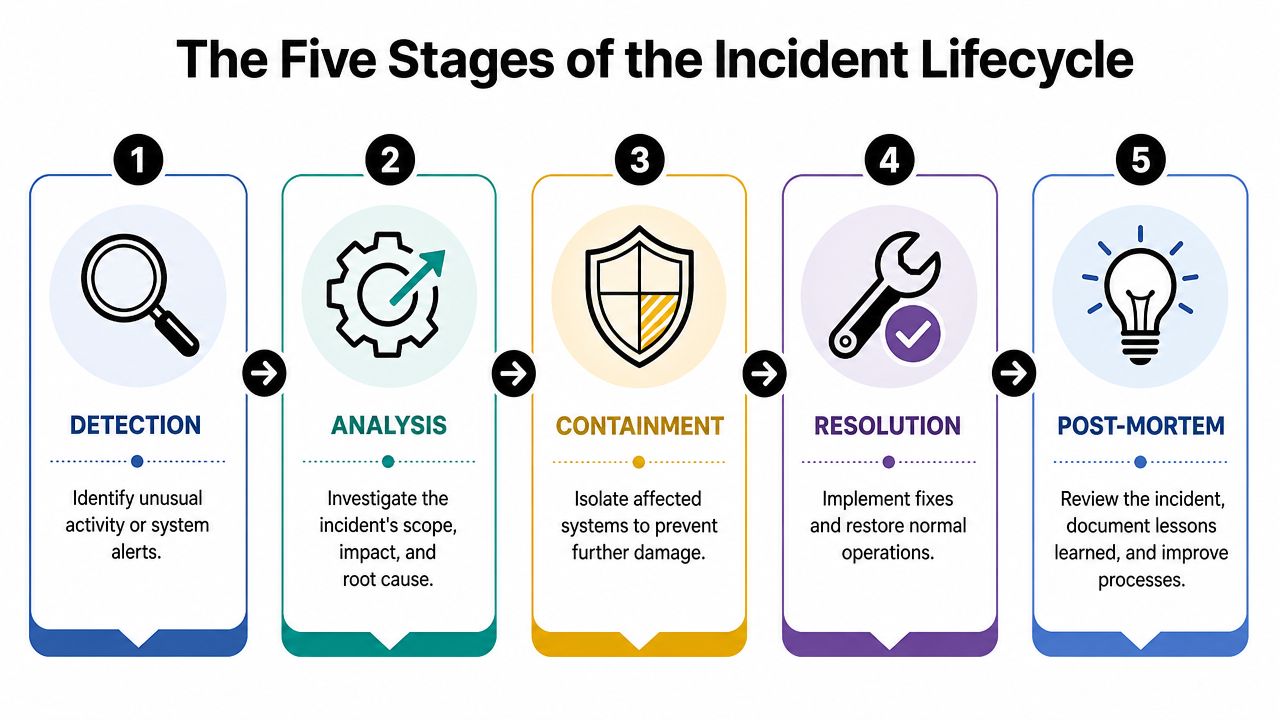
Serious teams need a lifecycle they can run under pressure without debate. ISO 27035 gives you that backbone. According to the standard, incident management follows five stages: Plan and Prepare, Detect and Report, Assess and Decide, Respond and Recover, and Learn Lessons, as summarized in this ISO 27035 incident management overview.
A simple visual helps anchor the flow.
Plan and prepare
Organizations often underinvest. They want to get better at response without doing the slow work of preparation.
Preparation means:
Define ownership: Every critical service needs an on-call owner and an escalation path.
Write playbooks: Common failures should already have diagnostic steps, rollback guidance, and communication triggers documented.
Set logging standards: If logs and traces are inconsistent, responders lose time reconstructing basic facts.
An incident response plan should also connect tightly to the broader incident response discipline in engineering and security, because many production outages blur into security, compliance, or vendor risk quickly.
Detect and report
Detection is where observability earns its budget. A signal comes in from monitoring, logs, customer reports, or internal staff. The mistake here is treating every alert like an incident or, worse, treating every customer complaint like a support ticket with no engineering path.
Good detection does two things well. It captures the signal, and it routes it without distortion.
The first report is usually incomplete. Your process shouldn't require perfect information to start doing useful work.
This walkthrough is useful context for teams that want a visual explanation of the flow from alert to recovery.
Assess and decide
This is triage. You decide whether the issue is real, how severe it is, what services are affected, and who needs to join. The strongest teams don't crowd the bridge. They mobilize only the roles needed to diagnose and contain the issue.
A useful way to think about it is an emergency room model:
Stage | Core question | Immediate output |
|---|---|---|
Assessment | Is this a real incident? | Declared incident or false positive |
Severity | What business impact is confirmed? | Priority level |
Mobilization | Who is needed right now? | Active response roster |
Respond and recover
Response is where discipline beats heroics. Microsoft's guidance is clear that teams should apply verified fixes through team-specific scripted procedures, use logs and monitoring to guide investigation, and include explicit rollback steps in case a change makes things worse, as outlined in Azure's incident management design guidance.
That means your responders shouldn't freestyle in production. They should:
Contain the blast radius
Apply the safest verified fix
Validate service recovery
Roll back quickly if the change fails
Learn lessons
Closure isn't “the graph looks better.” It means validation checks passed, impacted users were informed, and the incident record includes the trigger, triage decisions, containment steps, and final resolution. That same Microsoft guidance also emphasizes documentation as a feedback loop that improves future detection and response.
If you skip this stage, you don't have incident management. You have repeated exposure with better storytelling.
Assembling Your Incident Response Team Key Roles
Teams don't fail during incidents because they lack smart people. They fail because smart people pile into the same channel with overlapping authority and mismatched assumptions.
You need defined roles. Not corporate theater. Real roles with clear decision boundaries.
The incident commander keeps people from working at cross purposes
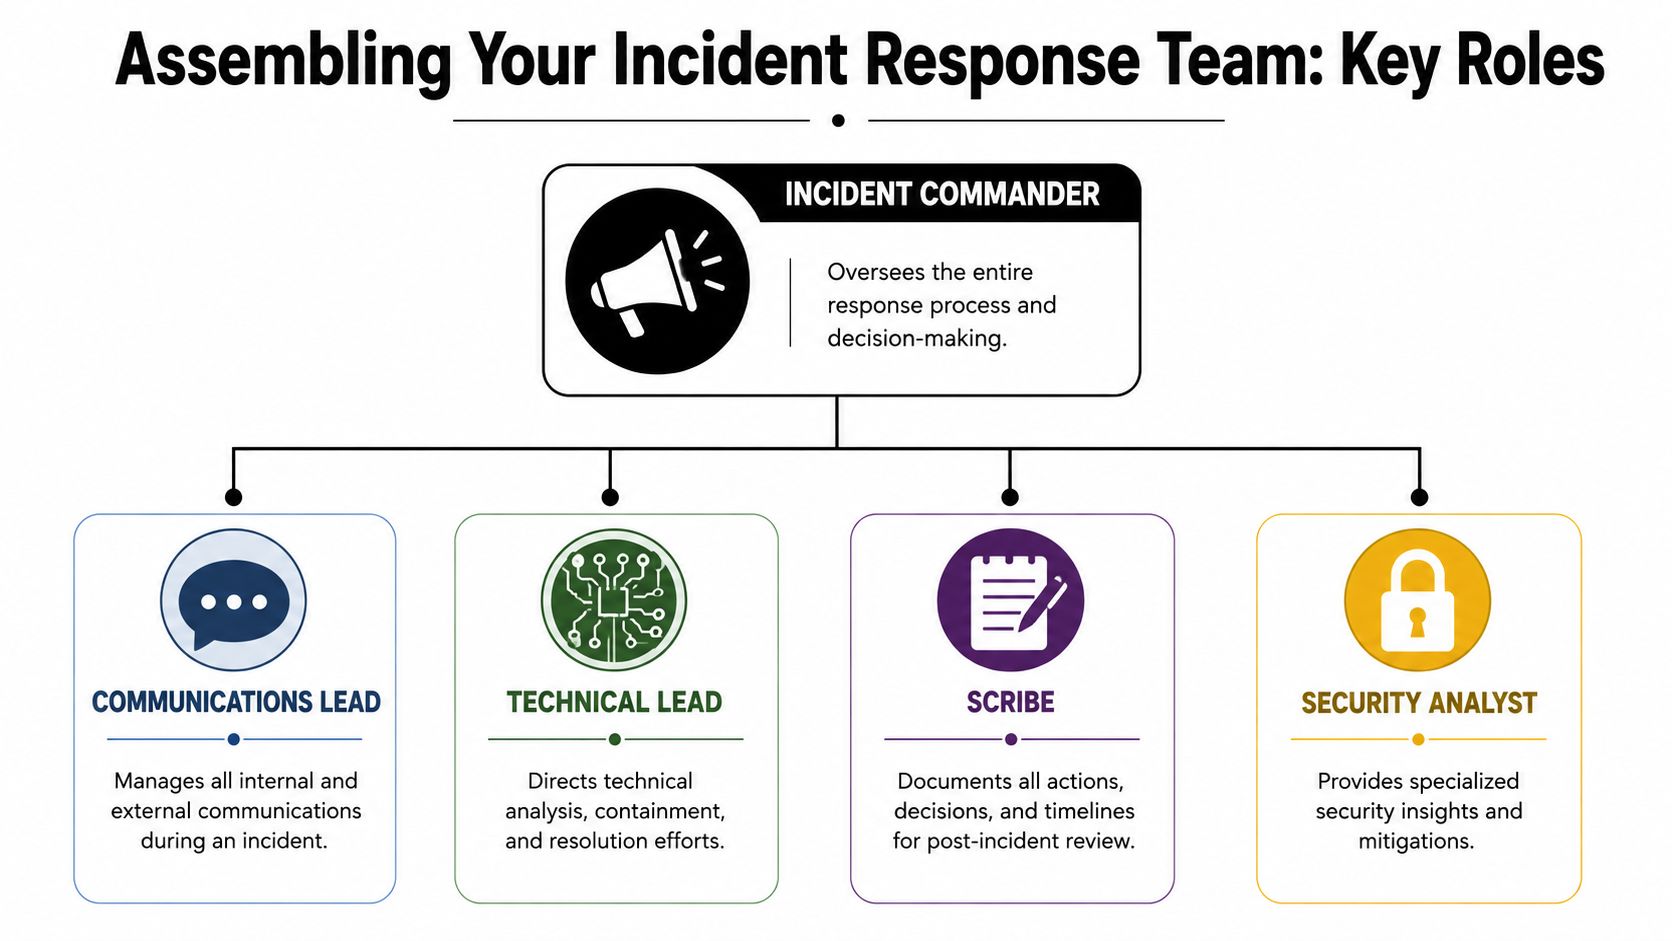
The Incident Commander is the control point. This person doesn't have to be the deepest technical expert in the room. They do need the authority to set priorities, assign owners, stop random work, and decide when to escalate.
If you don't appoint one, the loudest engineer often fills the vacuum. That's risky. Strong technical instincts don't automatically translate into strong coordination.
The Incident Commander should own:
Scope control: What's in the incident and what's not.
Decision rhythm: When the team gives updates and who takes action next.
Escalation: When to bring in more expertise, leadership, support, or legal.
Exit criteria: When service is stable enough to close the incident.
Calm beats brilliance in the command role. You want someone who can reduce noise, not add to it.
The rest of the team should be small and explicit
A lean incident team usually outperforms a crowded one. These roles matter most:
Technical Lead: This person drives investigation and remediation. They're often an SRE, platform engineer, senior backend engineer, or a domain expert for the affected system.
Communications Lead: They manage updates to leadership, support, customer success, or customers if needed. Engineers should not be context-switching into stakeholder messaging every few minutes.
Scribe: This role is underrated. The scribe records timestamps, actions, decisions, and unresolved questions. Good post-incident reviews depend on this record.
Subject Matter Expert: Bring in an SME for narrow issues like database failover, Kubernetes scheduling, cloud networking, identity systems, or payment processing.
Security Analyst: If there's any sign of unauthorized access, data exposure, or suspicious change activity, security needs to be inside the response, not waiting for a summary later.
A compact structure works because each person knows why they're there. Confusion drops when responsibilities are explicit.
Here's the blueprint I recommend:
Role | Primary job during the incident | Failure if missing |
|---|---|---|
Incident Commander | Coordinate decisions and priorities | Conflicting workstreams |
Technical Lead | Diagnose and direct technical fixes | Slow or misdirected remediation |
Communications Lead | Keep stakeholders aligned | Mixed messages and loss of trust |
Scribe | Capture timeline and actions | Weak postmortems and poor handoffs |
Don't assign titles and assume the job is done. Run simulations. Rotate command. See who can lead under stress.
Measuring Success KPIs SLAs and SLOs
If your program only measures “how many incidents happened,” you're managing volume, not reliability. Useful measurement starts with prioritization, then ties operations to customer impact.
Start with priority then measure the system
ITIL gets this right. Priority should come from a defined impact and urgency matrix, not from user self-selection, and teams should track MTTR segmented by priority, first-contact resolution rate, and SLA compliance per tier, according to this ITIL incident management best practices summary.
That principle matters because engineers need a shared rule for what gets attention first. A noisy executive complaint shouldn't outrank a quiet incident that breaks revenue-critical workflows.
Atlassian's incident management guidance adds the business lens: incidents should be prioritized by direct operational impact, the number of people affected, applicable SLAs, and potential financial, security, or compliance implications, as described in Atlassian's incident prioritization guidance.
A practical matrix usually looks like this:
High impact, high urgency: Revenue path down, core authentication failure, widespread user disruption
High impact, lower urgency: Partial degradation with workarounds
Lower impact, high urgency: Issue affecting a small but critical internal function
Lower impact, lower urgency: Isolated bug, no major service effect
If your organization is building a broader reliability program, this reliability engineering overview is a useful companion because incident metrics only make sense inside a reliability model.
SLOs guide engineering SLAs define the promise
MTTR still matters because it tells you how long customers or internal teams stay exposed after an incident begins. The 2024 incident management whitepaper found that MTTR is the most popular performance indicator, used by 86% of respondents, and it remains the clearest operational measure of recovery efficiency.
SLOs and SLAs serve different audiences:
SLOs are internal targets tied to service quality. They tell engineering what healthy performance should look like.
SLAs are external commitments. They define what customers can expect and what happens if you miss the mark.
Nobl9's guidance is especially useful here. It recommends formalizing Service Level Objectives across multiple monitoring tools so infrastructure metrics and events can be tied back to service quality and incident impact. That's how teams avoid chasing technical noise that doesn't affect users.
If an alert can't be mapped to service impact, it probably doesn't belong on your primary incident path.
Track fewer metrics, but make them decision-grade.
Your Toolkit Essential Tools and Runbook Examples
Tools don't create resilience. They expose whether your operational habits are sound. Buy too much tooling before you define ownership and you'll get expensive confusion.
The stack you actually need
You need a functional stack in four categories.
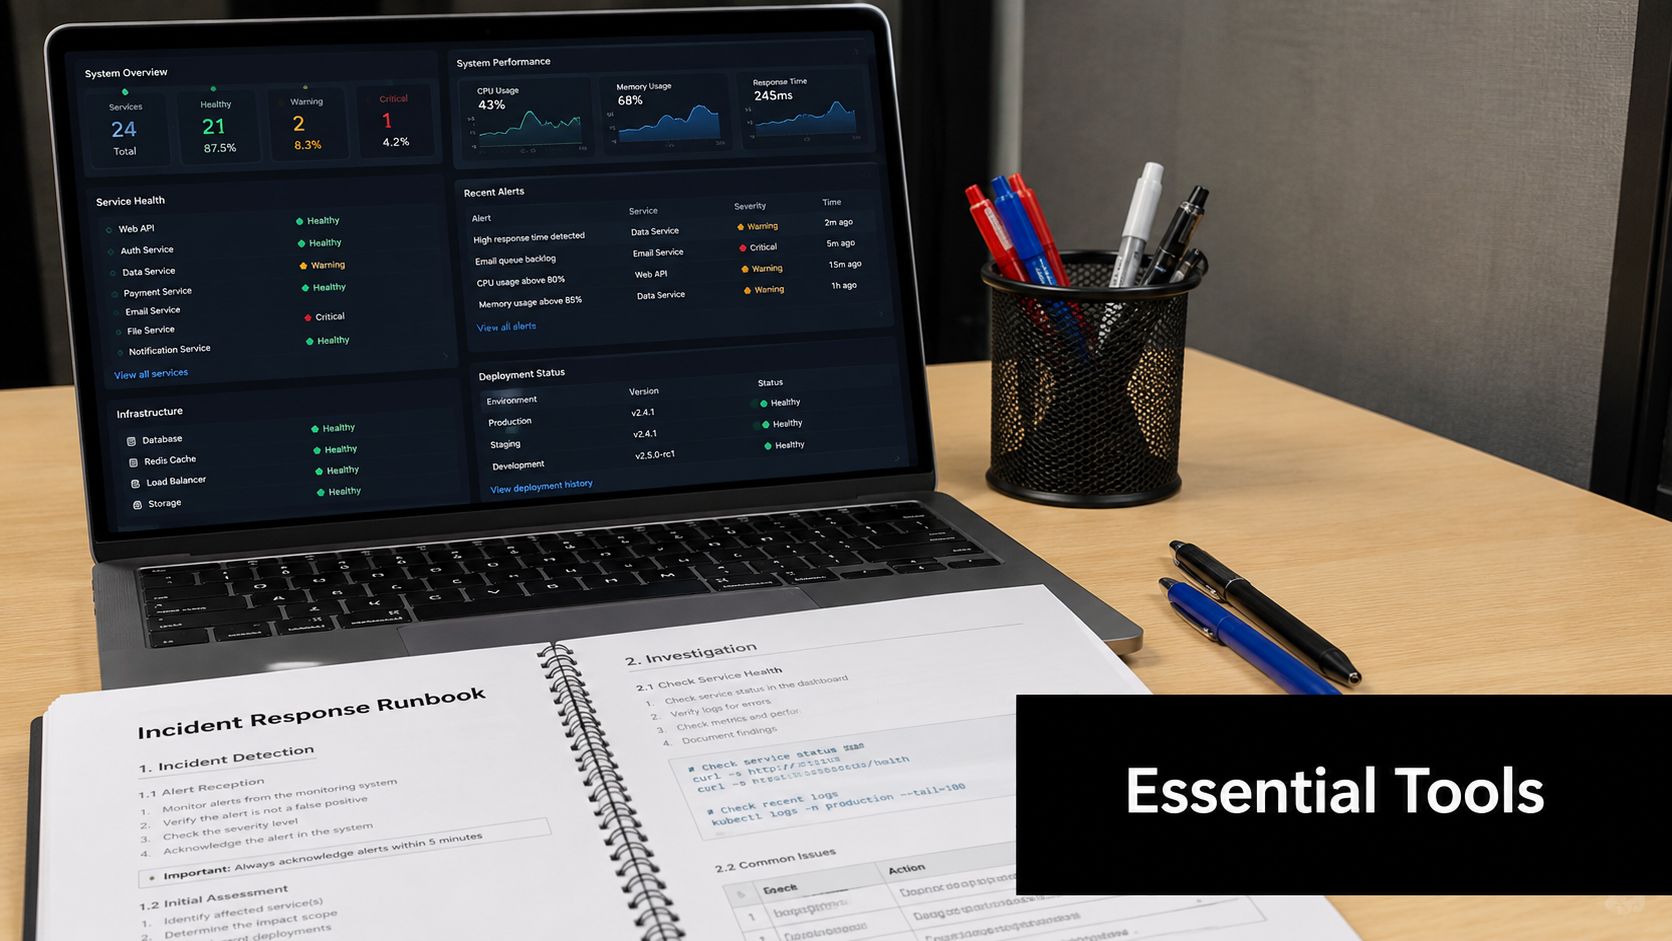
Observability tools: Think Datadog, New Relic, Grafana, Prometheus, Elastic, OpenTelemetry. These give you metrics, logs, traces, and event visibility.
Alerting and on-call systems: PagerDuty and Opsgenie are common examples. Their job is routing, escalation, and ensuring alerts reach a human who can act.
Collaboration and incident coordination: Slack, Microsoft Teams, Zoom, incident timelines, and status tooling all fit here.
System of record: ServiceNow, Jira Service Management, or a dedicated incident platform should hold the official incident log, assignments, decisions, and closure notes.
You also need runbooks. Not vague troubleshooting notes. Runbooks that say exactly what to check, how to validate a hypothesis, what commands or dashboards to inspect, what rollback path exists, and when to escalate.
A runbook example for database saturation
Here's a simple example for a database saturation incident affecting API latency.
TriggerAPI latency alert fires and application error rate rises.
Initial checks
Confirm scope: Check whether latency affects one service or multiple services.
Inspect database health: Review connection pool saturation, query latency, replication lag, and storage pressure in your monitoring platform.
Check recent changes: Look for deploys, schema updates, traffic shifts, or batch jobs.
Containment options
Pause non-critical workloads: Suspend heavy background jobs or reporting tasks.
Reroute traffic carefully: Shift reads to replicas if your architecture supports it.
Scale only if understood: Adding capacity without understanding the bottleneck can hide a bad query and make follow-up harder.
Resolution path
Kill or throttle the runaway query if confirmed.
Roll back the deploy if a recent change caused the issue.
Validate recovery by checking latency, error rate, and backlog drain.
Closure checklist
Confirm customer-facing recovery.
Record the trigger, actions taken, and final cause.
Schedule follow-up work for query optimization, index review, or load test gaps.
A good runbook reduces cognitive load. It keeps a tired engineer from improvising across five dashboards while leadership asks for updates every ten minutes.
Hiring for Resilience The Underrated Skill of Incident Response
Most incident management content obsesses over ticket flow and tools. That misses the failure mode I see most often in scale-ups and hybrid teams. The weak point is the human handoff.
When incidents hit, teams rely on shared context. Contractors, new hires, rotating platform engineers, and external specialists often don't have enough of it.
Hybrid teams fail at the handoff not just the fix
This is the part most guides ignore. Data shows that 68% of production incidents in scale-ups stem from communication gaps between permanent staff and external contractors during critical alerts, and that observation is highlighted in Zendesk's discussion of incident management realities in modern teams.
That aligns with what engineering leaders see in practice. Existing playbooks often assume a stable incident team with deep system familiarity. Real teams are messier. A staff-augmented SRE may be excellent technically and still lose time because the ownership map is unclear, the service history lives in someone else's head, or the escalation path assumes internal tribal knowledge.
If you run a hybrid model, you need to design for continuity:
Shared runbooks: Contractors and permanent staff should use the same operational documents.
Service ownership maps: Every critical dependency needs named technical owners.
Embedded onboarding: Don't treat incident readiness as something engineers absorb by osmosis.
Engineer-to-engineer vetting: Resume screening won't tell you who can triage a live outage coherently.
Hire for judgment under pressure
The right incident responder usually has a mix of technical range and behavioral discipline. I look for:
Diagnostic thinking: Can they narrow possibilities quickly without jumping to pet theories?
Communication clarity: Can they explain what's known, unknown, and next in one minute?
Operational restraint: Do they know when not to change three variables at once?
Systems context: Can they reason across app, infrastructure, dependencies, and user impact?
Your interview process needs to test that. A structured approach helps. If your hiring loops are too improvisational, this piece on how to improve your tech interview process is worth reviewing because incident-ready talent doesn't reveal itself through trivia or generic coding screens.
Hiring for incident response means hiring for composure, communication, and systems judgment. Pure coding skill isn't enough.
I'd go further. In reliability-heavy environments, talent quality is part of the incident management system itself. You can't patch over weak judgment with more dashboards.
Build Your Resilient Future with Elite Engineers
A modern incident management program is built on a few foundational requirements. You need a clear lifecycle, explicit roles, meaningful metrics, and runbooks that responders can trust when pressure spikes. You also need observability that maps technical signals to actual service impact.
That observability piece matters more than many teams admit. Expert-level programs require monitoring across the MELT framework, Metrics, Events, Logs, and Traces, with alert thresholds tuned tightly enough to reduce noise and help teams identify the right signals, as described in Nobl9's guidance on expert incident management programs. If your alerts are sloppy, your response will be sloppy.
Resilience is a systems problem and a talent problem
Resilience also depends on what happens after the outage. Effective reviews should document the exact sequence of events and resolution steps, audit categories and assignment rules, gather feedback from agents and users, and test process changes on a smaller scale before full rollout, as outlined in InvGate's post-incident improvement practices.
That operational maturity should sit beside recovery planning. If your team is tightening incident discipline, it should also revisit disaster recovery planning for engineering organizations, because incident response and recovery capability are tightly linked.
The final point is the one most organizations resist. Process matters. Tooling matters. But the floor and ceiling of your incident program are set by the engineers carrying it out. Teams become resilient when they have people who can prevent avoidable incidents, triage ambiguity, communicate clearly, and recover services without creating new failures.
TekRecruiter is technology staffing and recruiting and AI Engineer firm that allows leading companies to deploy the top 1% of engineers anywhere. If you need stronger SRE, DevOps, platform, cloud, or AI engineering capability to build a more resilient incident management program, TekRecruiter connects companies with elite engineering talent built for high-stakes systems and high-pressure delivery.
Comments